alright this is the prompt i gave this is good enough as context to anyone reading this too lol
we want to train a model for nerdle. Propose an initial environment scaffold including relevant tools, and come up with a good method to generate a small sample synthetic dataset. Run a quick eval baseline, inspect the results, and then decide how we should iterate on refining the implementation.
now the idea for the thing i want it to work on is simple nerdle idk if you know it’s like wordle but instead of a word you have an arithemetic equation. here’s the premise of the game if you don’t know i am thinking of a simple math equation it uses operators like ’+ - / * =’ it can have 0-9 any number on any spot we have 8 spots like wordle you have to guess the correct equation. it follows bodmas rule if you give it an equation like 7-4/2+1=6 it considers it sequentially with bodmas no brackets are allowed you have to guess each spot correctly like wordle i will give you hints as 0 meaning it is on correct thing and correct spot,1 meaning correct thing wrong spot, 2 meaning incorrect thing and incorrect spot you can use your artifacts for calculator or whatever if you need it between thinking think hard and give correct guess you get 8 tries. guess for spots ok so [1 ][2 ][3 ][4 ][5 ][6 ][7 ][8] each spot can be any number between 0-9 a or an operator the equation must be valid and do not start with an operator the result should be in the 8 spots including the =
now we first need to SFT that model so it gives structured output we can’t do this using prime RL so how about we set it using our own synthetic dataset for this and we just train it or can we directly RL without structured output ? actually we can’t sft on prime RL so we just do direct RL lora ig. so we need to have a format reward.
we want to allow tool use such as calculator in the model too the end goal is to have a capable model of guessing the equation in given tries. we can figure the env and reward structure together
do not edit any files first give me what your approach is going to be then we will discuss and only then you can build that structure
setup
i made a prime env and tested with a hardcoded a random guesser script just to check random results.
after that i also ran a smoke eval test and this motherfucking 502 error is just messing with me it shouldn’t even exist. fixed that shit. now the next error was
there was a new issue in the env it was only doing 1 turn because if it didn’t call a tool it would stop the rollout.
ok the bug was in function call, some weird thing was happening where it couldn’t parse the function call or was calling it in incorrect way and hence empty model response as soon as i removed it, it started giving long responses. but now with the new prompts it’s taking a hell of a lot of time for each rollout with feedback and stuff(which is good ig).
openrouter is just incredibly unstable, i changed the entire env to be like the wordle env with textarena or whatever and it worked one time then it suddenly is giving empty responses agian. i have now spent an unnecassary 3 days on this bs env it’s assinging rewards and everything but nthe fucking model won’t budge on openrouter.
the final issue was actually a prime thing it wasn’t correctly doing retrying what i had to do was manually log every req and see exactly what happened when model returned empty and i designed a failsafe which gracefullty continues the multiturn env. rewards etc are working fine. i am going to start training for this now.
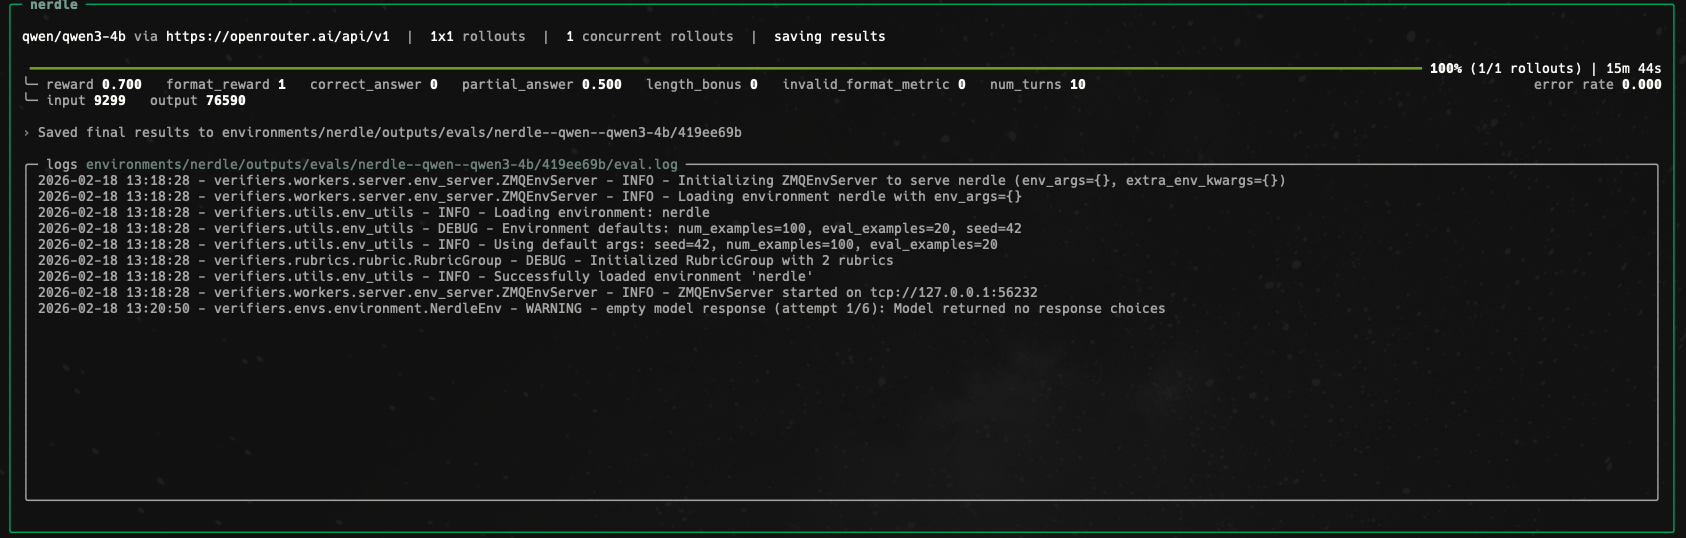
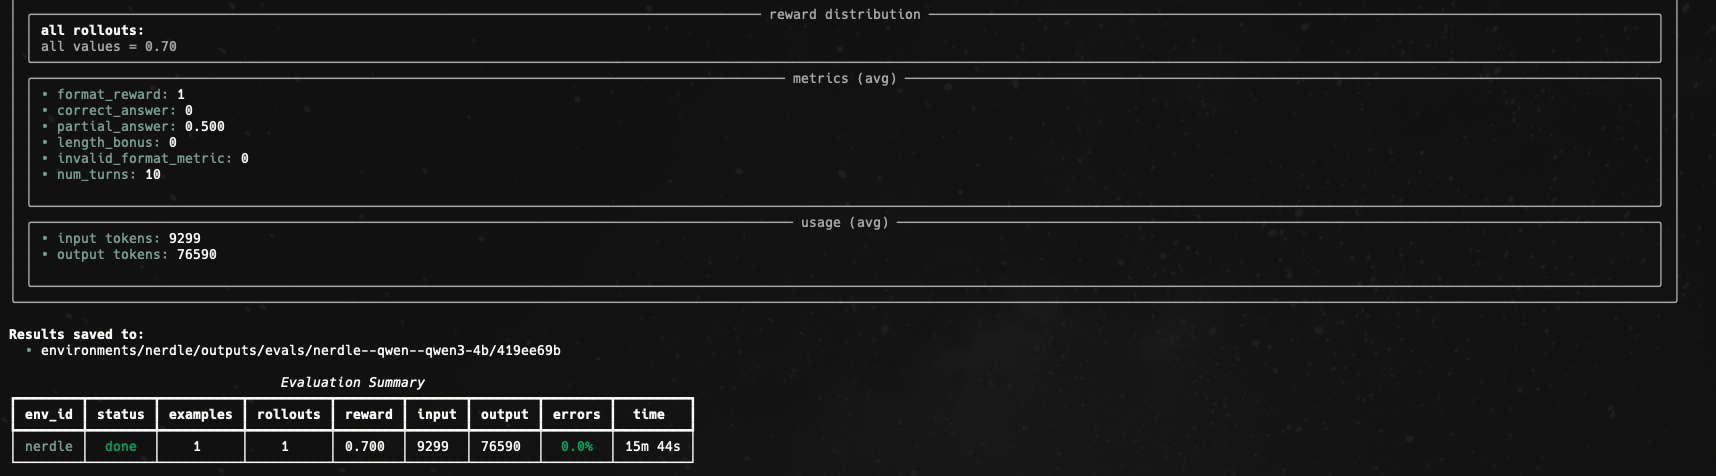 it works we move to training now
training
i already have the nerdle env pushed i am gonna use qwen3-4b-thinking
ok i started training with wandb key but it failed because the env used something to convert the openai tool schema. but apparently the rl doesn’t support it so maybe i should check if that works correctly or what
i am getting a lot of issues with tool definition and control. this should be quite controlled in the sense define function let which prime rl converts later
Note: this is what prime does latest i think i was using an older version of prime rl and hence had to fix. nonetheless this incompatiblity between RL and envs still stands ig
fukc this is like really slow since it’s multi turn it and i took max_tokens=30k maybe i should reduce it to 8k
oh lawd it’s the null response error
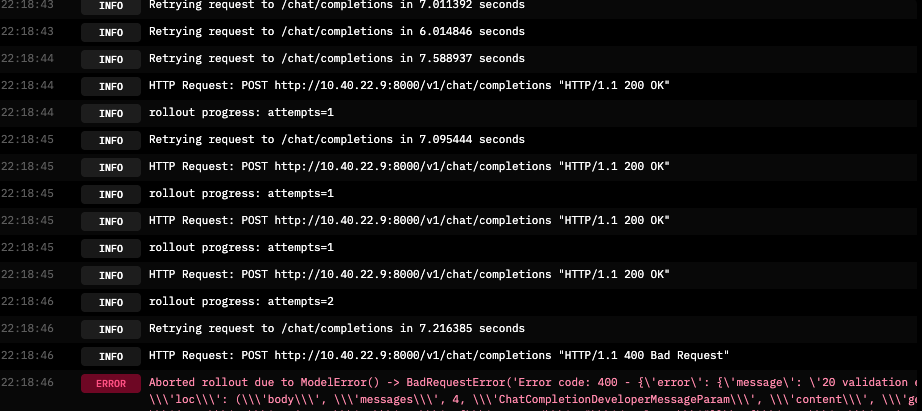 i’m gonna kms. i am starting to think it’s a common issue on this dumb fuck a model
oh fuck it’s working LET’S FUCKING OGOOOOO
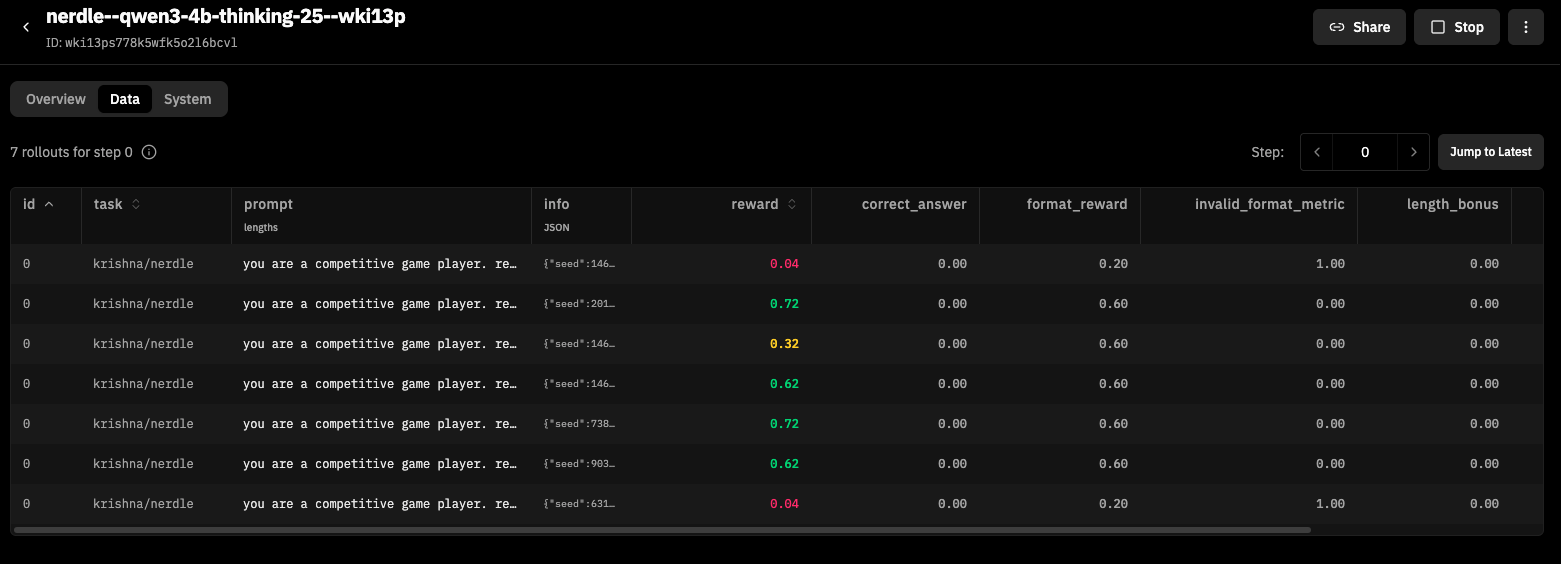
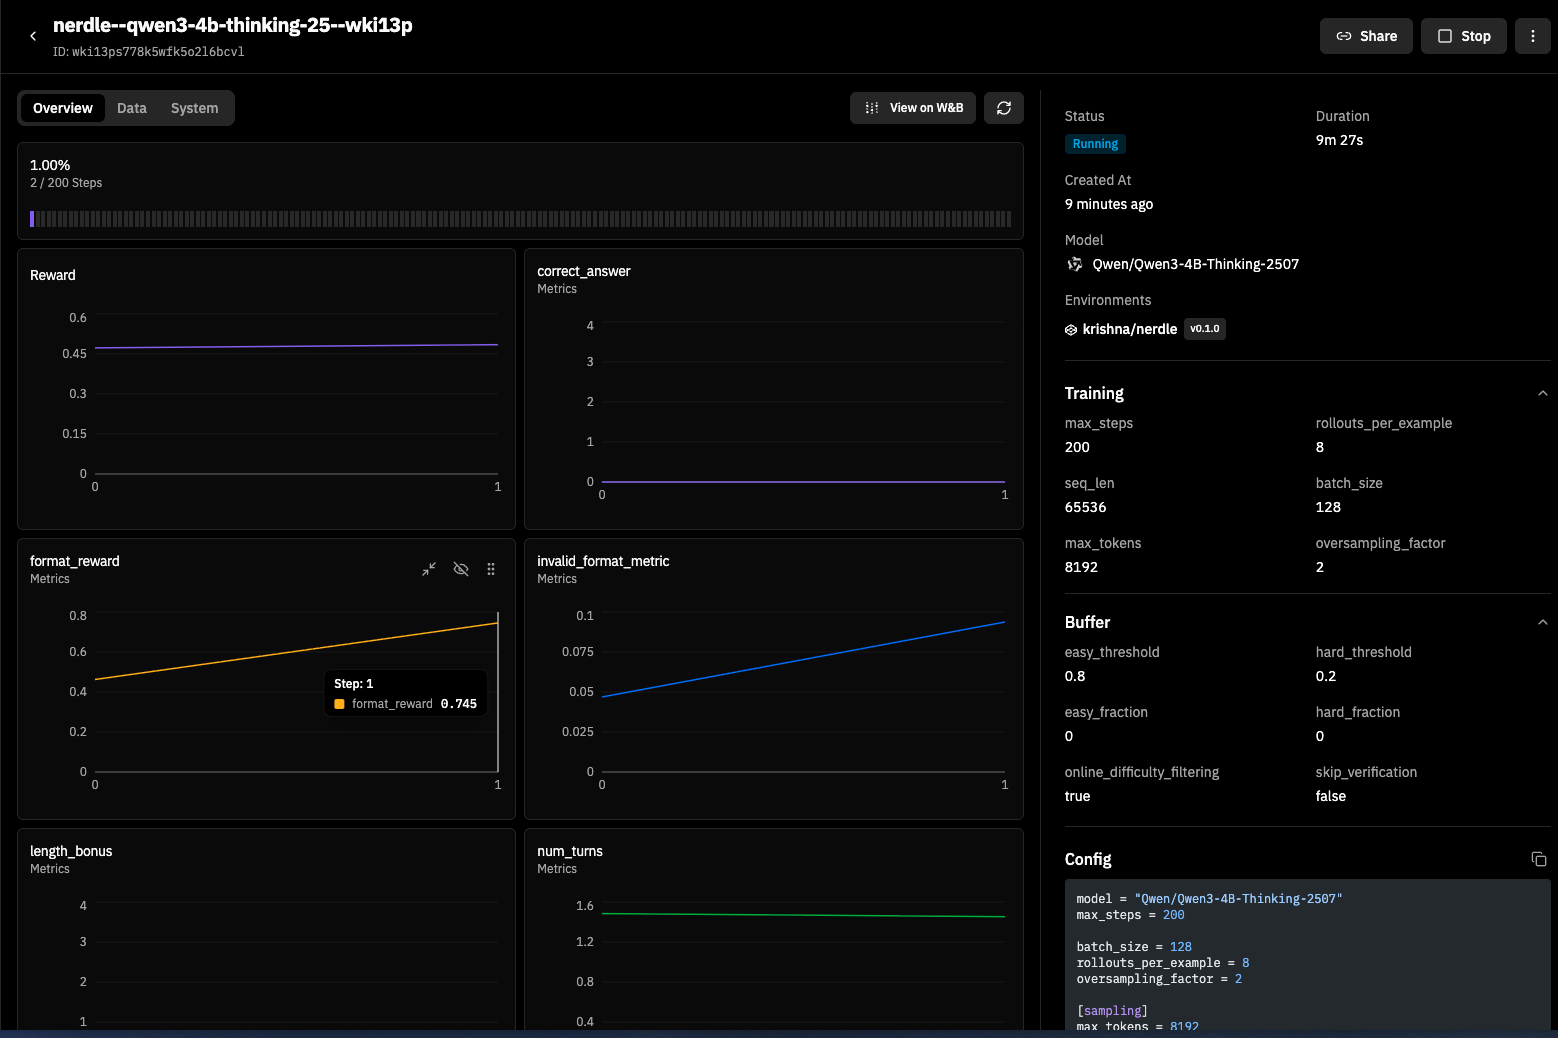
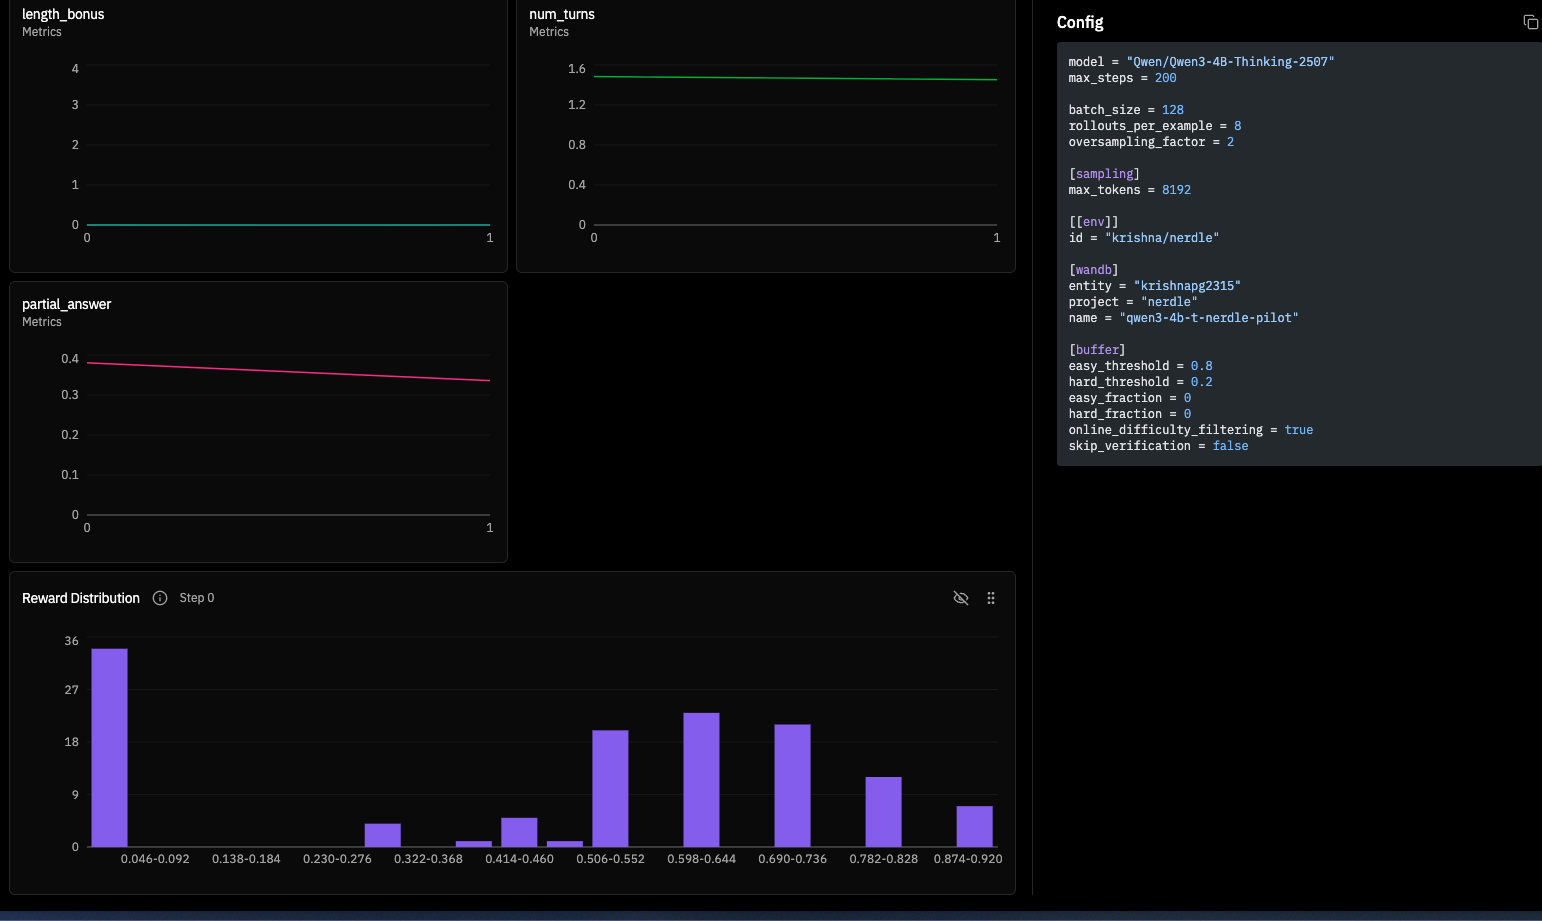
alright now the actual work would begin
for 28 steps it has not gotten too many correct ones yet. this should have wandb and the ability to check up the models correctly somewhere during the model just to check samples and a ui over it.
since the last run was going good but there was no actual improvments on the slow ass rollouts and most of the rollouts are not even more than 2 convos long i added a little more reward towards more guesses where it scales it on the number of guesses (non linearly ofc since we don’t want it giving too many guesses either)
but i stipped the previous two hour run and it can’t be continued on hosted damn so i gotta restart a new one from scratch.
there is a slight chance that due to max_tokens=8192 it is exceeding the budget after two turns and hence failing after the two ones
ok it’s own step 12 right now i think i am gonna wait till step 20 and if the model is not doing good i will stop this run change it to max tokens 30k and only pass the think tokens from the last n number of turns in context
multi turn is too slow i am gonna make it single turn with histories being passed that should work. the current nerdle env is too slow change it to to make it single turn instead of multi turn and keep the history of each output and share it as user and assistant context for each turn so that way don’t have sparse reward with multiple turns per rollout instead each rollout is just a turn of conversation do not include invalid guesses in history context ok ?
alright it was faster than multi turn but not necassarily better
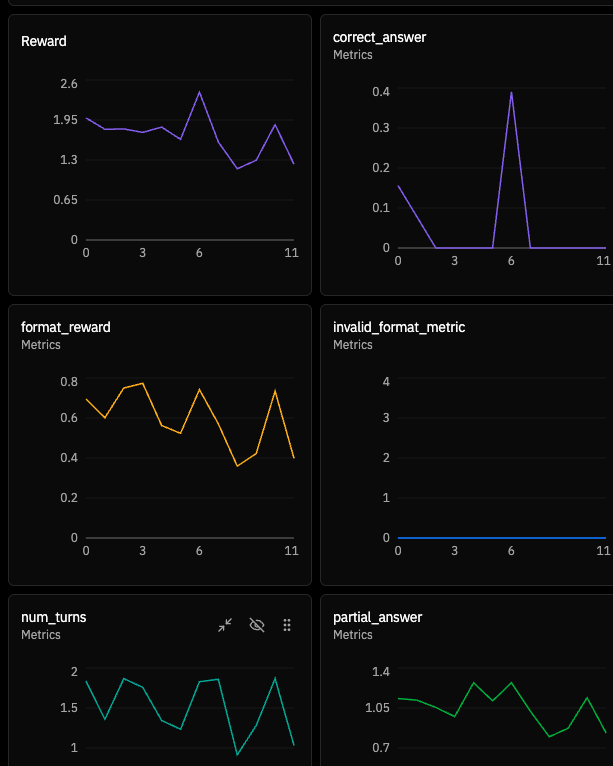
rewards went down so but not sure why. oh god i am a fucking retard. i changed the env to pass context history and do a new rollout each time the model guesses but the secret equation changes so the history is useless fuck. gonna fix that so it maintains the same secret for the history thread.
made these changes
- dataset no longer pre-fills
secret/history; it now only seedsthread_id+seed setup_statenow loads thread state from an in-memory store:thread_id -> {secret, history, rng}- prompt is rebuilt at rollout start from that thread’s current history
but this is make as you go env so if the server has some issues it’s gonna reset the entire memory (i doubt that would happen)
but i need to do something for parallel threads with the same context/history. maybe i can leverage this since we are doing grpo we just need the overall best right same policy can have different methods…
alright used parallel rollouts as same-state proposals with single-writer commit:
- each rollout reads same thread snapshot (
secret/history/version) - all rollouts get reward for grpo
- only rollout with matching
versioncommits history (cas + lock) - stale rollouts are ignored for state update (no overwrite race)
- added prompt
noncemarker so parallel proposals don’t dedup away
maybe i should have pre made the dataset because the initial load takes a lot of time maybe if i pushed a json file with the data. why is this off-policy though i don’t get it.
added a progress reward which is like if the current guess is better than the previous guess. i wisg the rewards shaped themselves man.