experimenting with jepa world model
i started by downsizing the model params because i wanted to run it on my mac just to see what happens what can it encode etc.
current debug-box setup:

**vit encoder**
- image size: `128`
- patch size: `16`
- encoder dim: `128`
- encoder depth: `4`
- encoder heads: `4`
- encoder mlp ratio: `4.0`
- output latent dim: `64`

**jepa world model**
- history size: `4`
- action dim: `4`
- latent dim: `64`
- dynamics dim: `128`
- dynamics depth: `2`
- dynamics heads: `4`
- dynamics mlp ratio: `2.0`
- dropout: `0.0`
- training loss: `latent_loss + 0.09 * sigreg`
- sigreg: `knots=17`, `num_proj=1024`

**decoder**
- input latent dim: `64`
- image size: `128`
- patch size: `16`
- decoder hidden dim: `128`
- decoder depth: `4`
- decoder heads: `4`
- decoder mlp ratio: `4.0`
- dropout: `0.0`

**train defaults**
- wm batch size: `4`
- decoder batch size: `8`
- lr: `3e-4`
- weight decay: `1e-4`
i should probably change the lr to be size appropriate but for now i am using the default ones given in the repository.
the vit and the world model are trained together only and these were the results of that run.
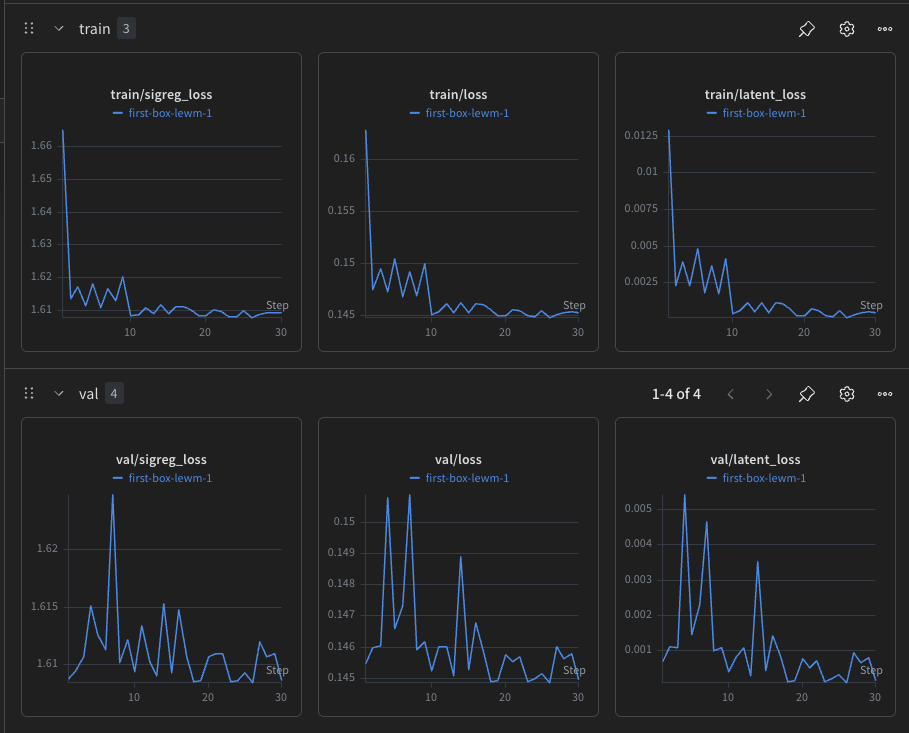
i am only using a debug dataset of 256 samples and running it for 30 epochs . using the same dataset from world envs genie debug that big box in a frame to move slightly because easier to compare. now i can’t directly visualise the results so i need to make a decoder first
the decoder
i first tried a simple decoder the original decoder i made was:
latent -> linear -> 8x8 feature map- then a few
convtransposeupsampling blocks - finally
conv -> sigmoidto get the image so basically a standard deconv image decoder from one global latent vector.
but as expected it was just a blurry mess. so i took the approach from paper using patched tokens with cross attention blocks.
both of them had the same faliure case the block was just on the average position and did not change based on the latent vector it’s own positon sort of like a weighted average of each position. time for normalization and regularization
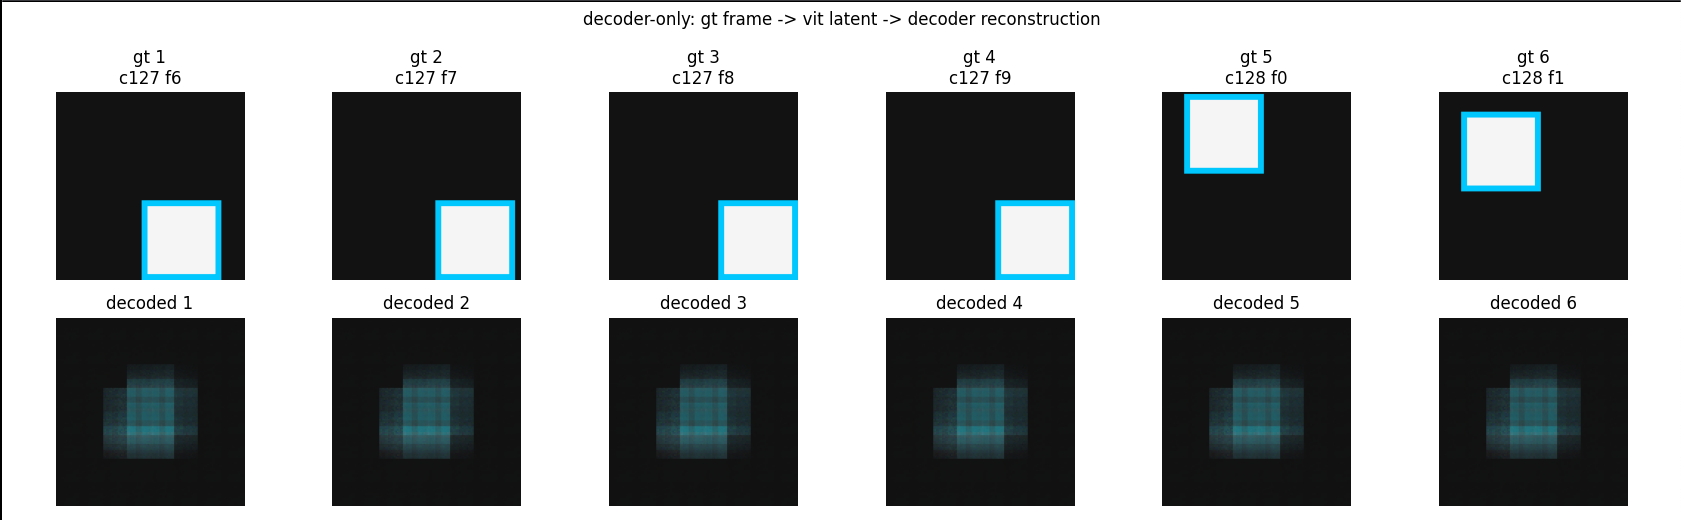
TinyViTEncoder was collapsing the whole patch grid into the cls token at decoder. then LatentDecoder got only one context token per frame, so every patch query attended to the same vector at decoder. that means spatial position was already gone before decode, so the decoder could only learn a canonical average image, which is why you saw the blurry centered box.
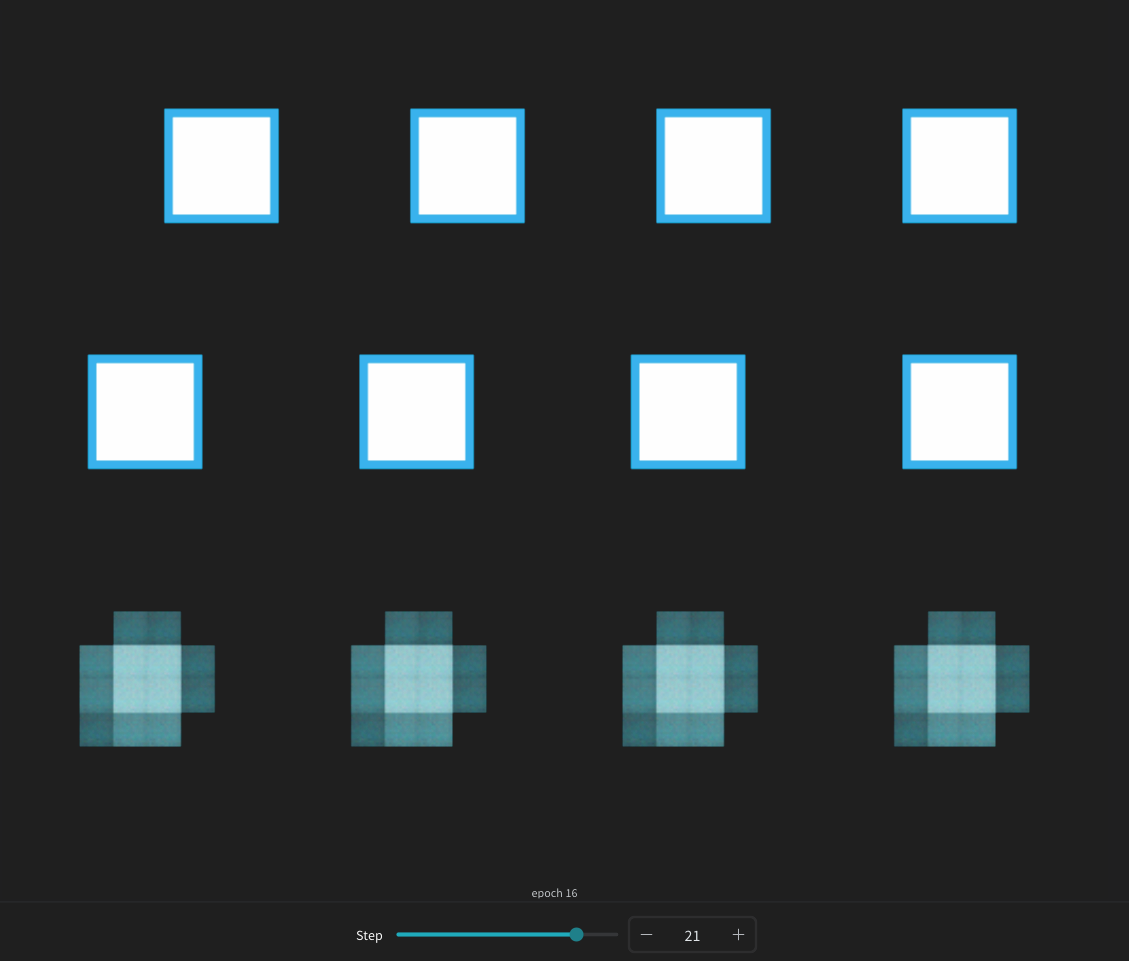
i am so retarded. now it should get per patch vit latents so that should allow for multiple decoding.
no luck same issue maybe it’s something i am blind to architecturally hmmm
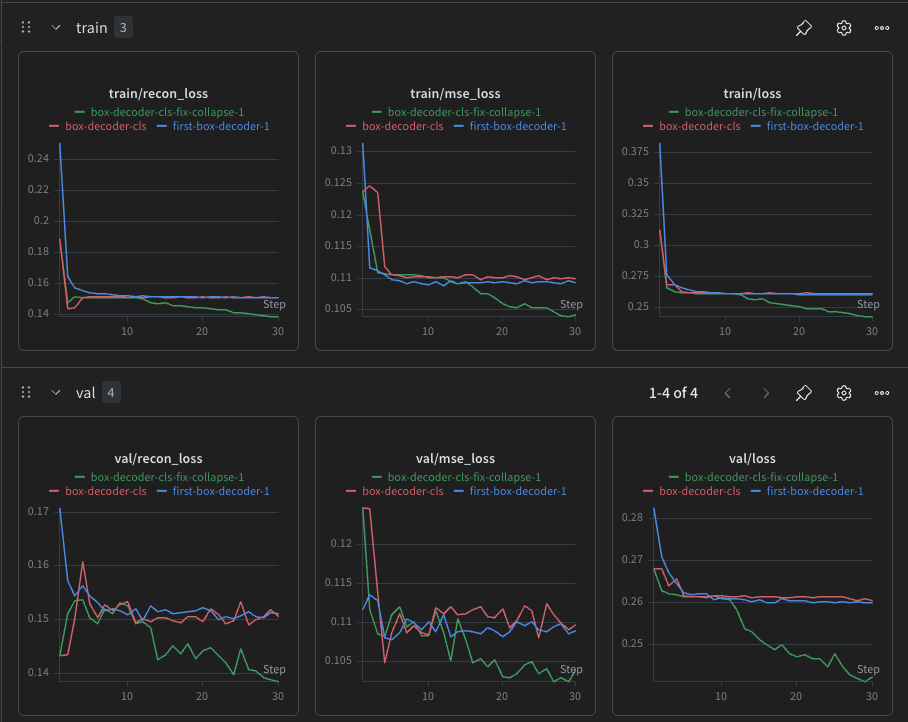
val loss is lower than other runs though.
alright i did a little x,y probing in the latents and also did some diagnostic logging.
it is definitely the encoder problem perhaps a collapse idk.
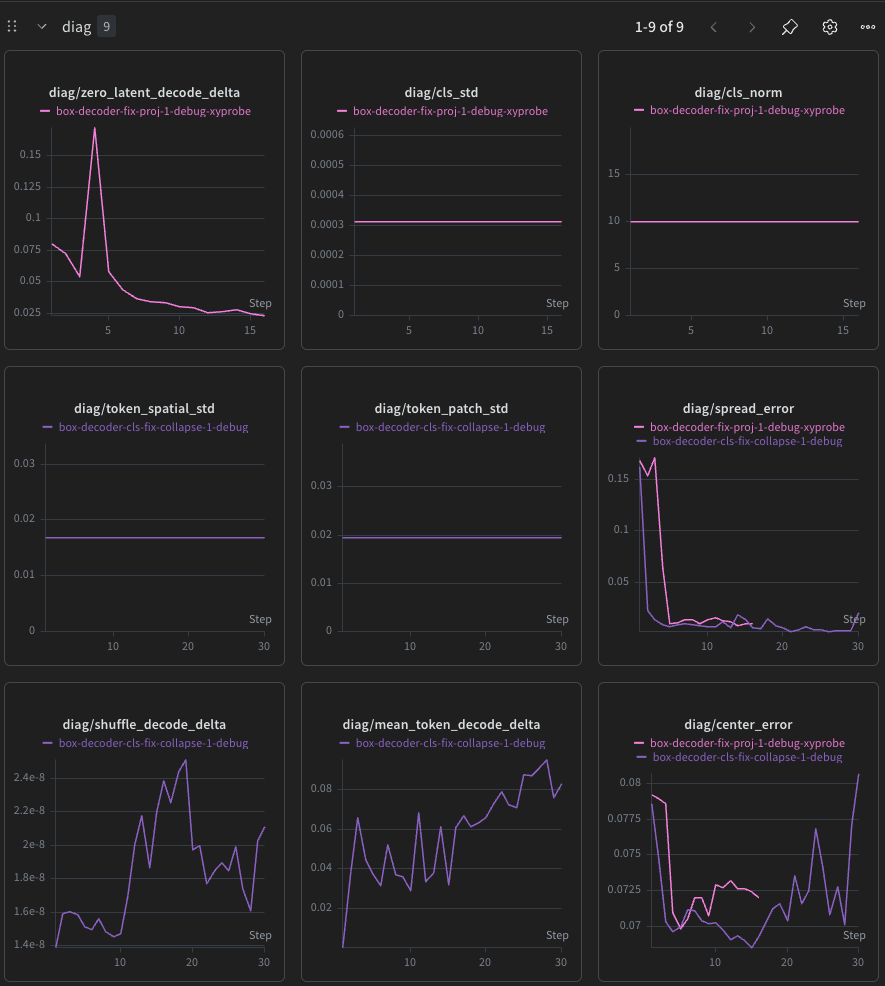
encoder problem
i trained a small encoder that has gradients flowing from the decoder itself so as to just check if it would even work on that small a model (feels trivial though) . and sure enough this performs quite well 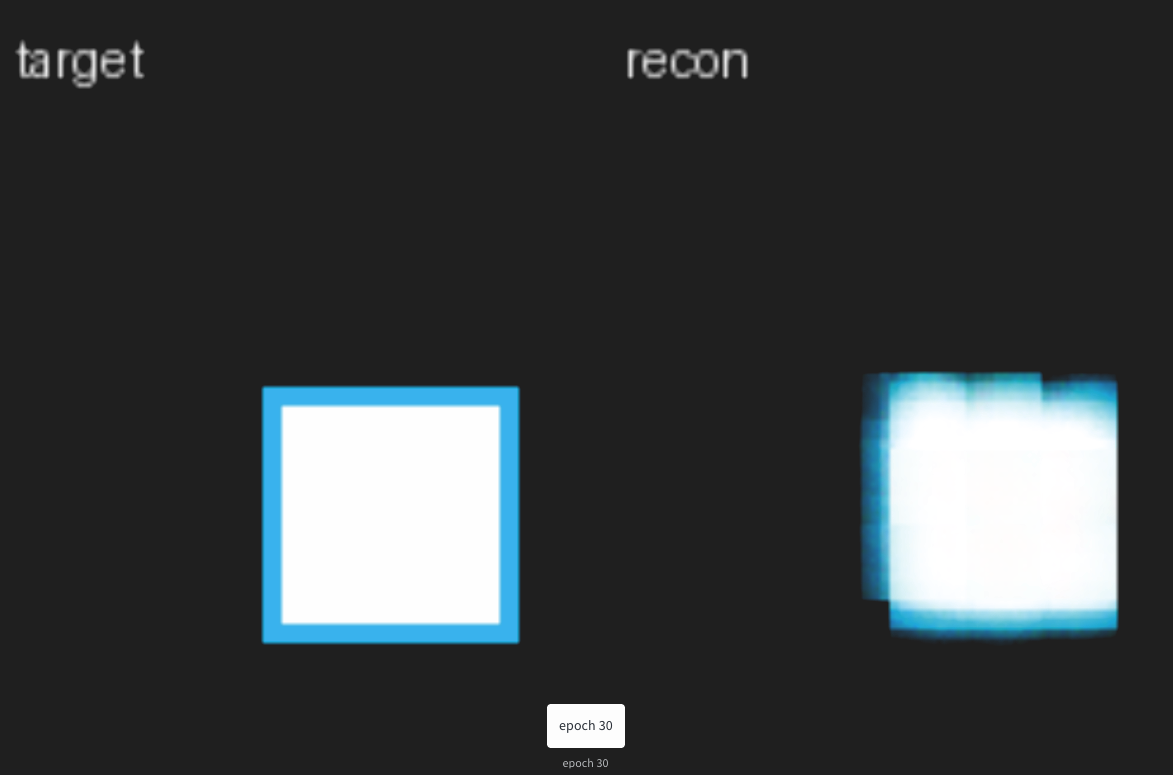
so it’s really the jepa gradients that the decoder can’t make sense of which ig tracks because the goal of jepa is not to have better visual representation it just needs to design the env around whatever the data is and try to emulate it? so the vectors aren’t exactly spatially sound. which would solve itself at scale but i need it to work on this how do i make it work on this ?
jepa just cares about how it manipulates that vector it shouldn’t matter where the vector comes from if i increase the depth of the model it should just be able to use it as is right? let me test that shit.
the reasoning is that jepa just needsa a visual representation into latent but there’s a good chance that the vit was trained with jepa because it needs to adapt to the dynamics , the actions and the history. so if it doesn’t work maybe i should not use a frozen encoder instead build on top of this.
HOLY SHITT IT WORKED HAHAHAHAH LET’S GOOOO
i mean it’s not perfect latents but it’s damn close.
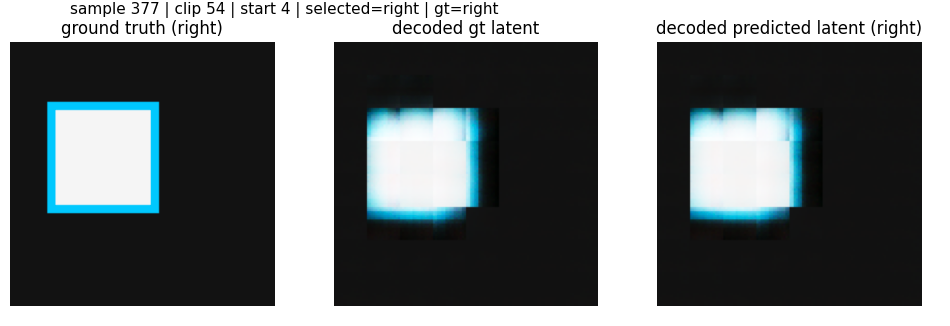
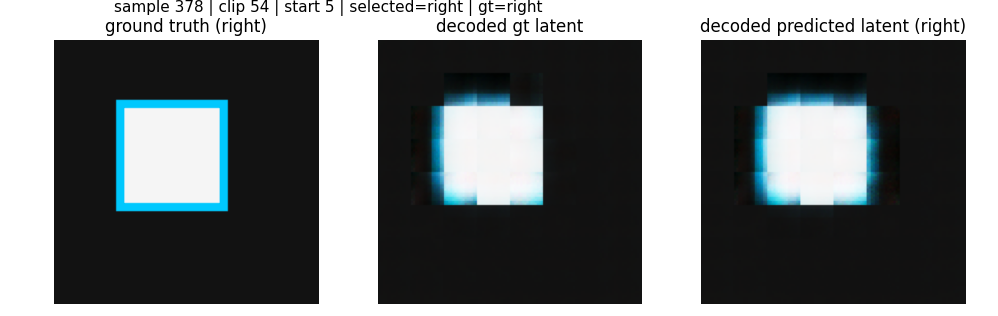
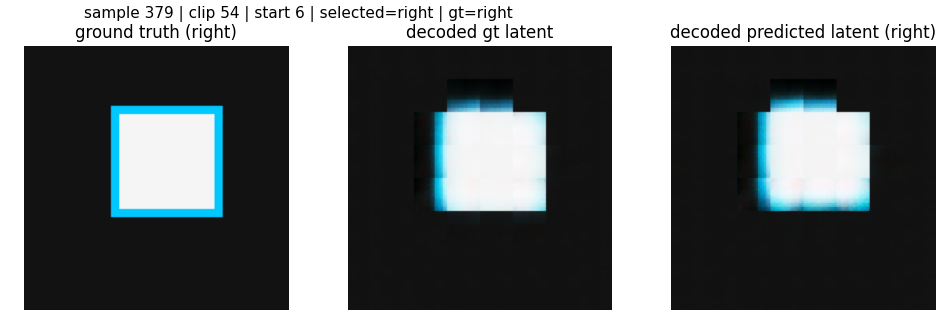
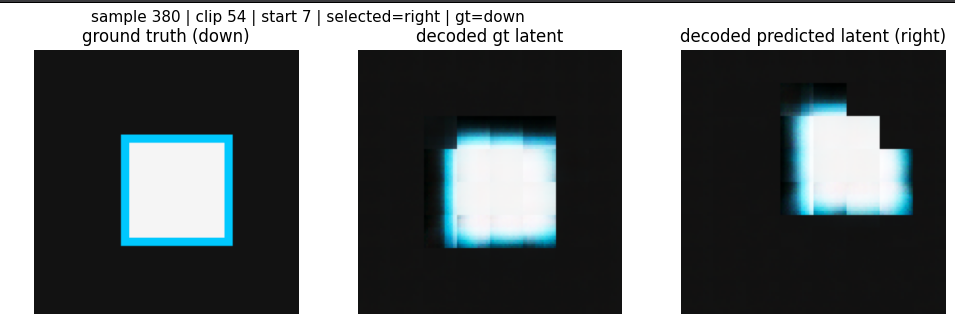
amazing lfg
well it was relatively easy i just had to figure out the decoder but i have the recipe now so. let me try to port it to some game maybe doom lol. gonna scale it accordingly.