so i was tired of just studying so i decided to make a project starting with a snake env… apparently its a little hard for RL to figure out but that’s ok i am a genius. i chose this project because once i have a good enough agent i can also use this to train a genie type model of a snake game. another reason to do this is because other people are starting to catch the glory of world models and i need to be faster.
i started by creating a snake game env in js (js because it’s easier to visualize for my shit)
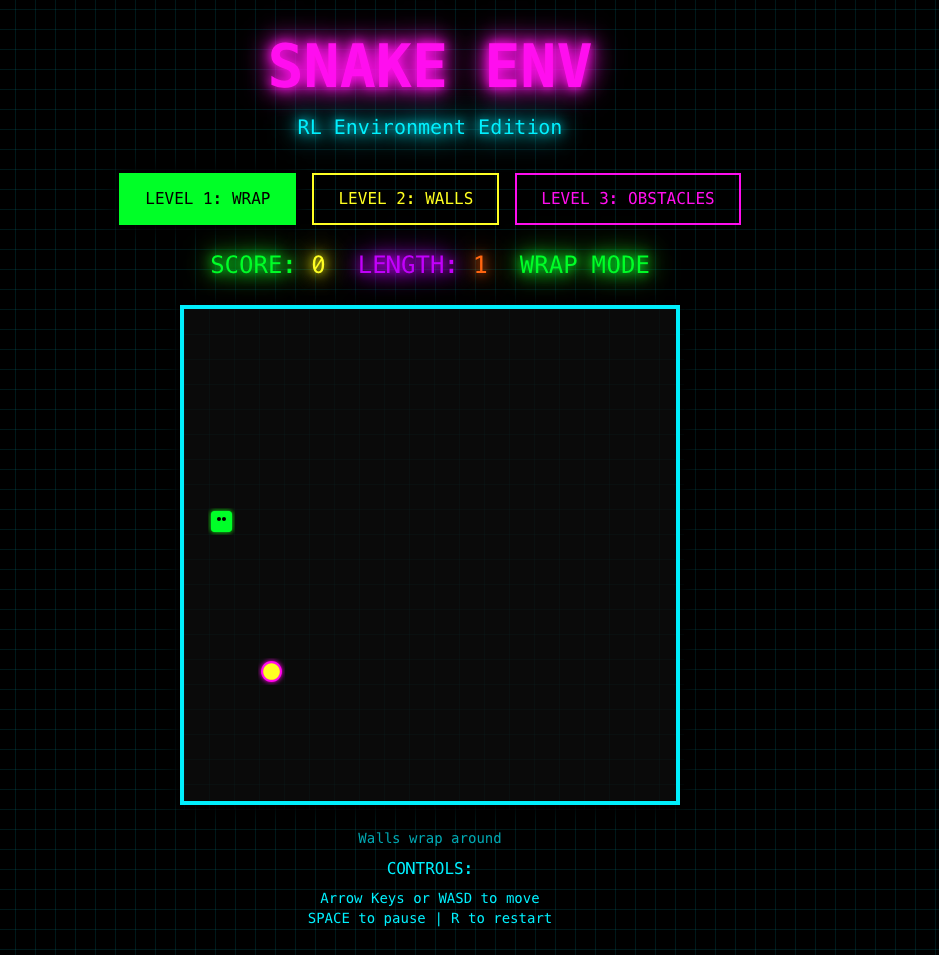 it has three levels
- death only by self collision
- death by boundary walls and collision
- walls and obstacles i wanted to do one by one training getting the model to actually move to increase
but the env itself had so many problems it took me a while to fix all that bs. anyways once done i started with a standard PPO algo and CNN for the model arch. CNNs are nice for visual tasks and then i thought maybe i can do like forward research to how much does transformer perform better and the grpo etc over this only.
i started with the raw code that gpt-5 gave. and got bs results i am too lazy to even pull the wandb results actually.
but basically the issue is the model is overfitting in one direction
when trained on level 1 it just moves in one direction so as to not die
there is better exploration in level 2 it tries to actually move but since the rewards are so sparse it keeps dying and mostly moves in one direction.
this is basically what happens in every run
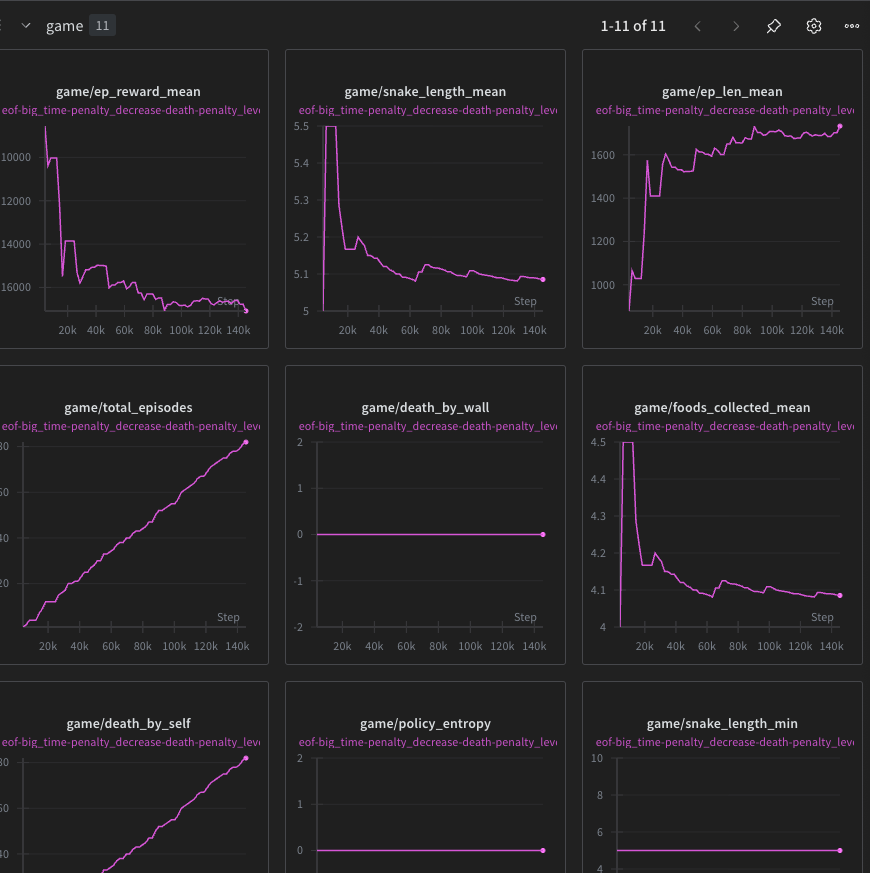
here’s a list of things i have tried so far in level 1
- hard positive on food +100
- just incentivises to move in one direction and not die
- manahatten distance algo rubric reward
- no effect but does help in level 2 exploration
- changing a bunch of coeffs
all around the thing with level 1 is not proper difficulty it can reward hack easily so RL models do need some kind of negative action space to realize what not to do. funnily enough training on level 2 and running in level 1 actually makes tyhe model perform better.
but due to the gross overfitting it keeps just doing one thing to the point where the random policy performs better…
i wasn’t logging it better up until now but i should
level 3 baseline
here on out i will train in level 3 for it to explore better because 300k steps had done some real good exploration techniques i wanna kind of start with a big food reward basically have it 100 again maybe it tries to perform better for that grradient. but if we are just taking the average then i don’t think that would do us any better hmm maybe not. the problem remains that its not getting enough food so i think a curriculum will be nice
curriculum
made curriculum stronger GAAAH JUST FUCKING EAT THE FOOD YOU DUMB MODEL
that didn’t work a lot bettert it just doesn’t eat food.
trying tighter clip and scale rewards with length maybe that does something.
ok upto 400k steps it starts to do a little better in level 1 but this because we are training it in 3 and it just knows it needs to move around in the box maybe i should train on level 2 instead
oh shit increasing food reward to 100 it’s actually trying to get it in the curriculum maybe i should train on level 2 it’ll perform better. without constant obstacle shit lol i’ll run this till 400k steps
uv run python snake_agent/serve_model.py --model checkpoints/big_run_mixed_5000-food/mixed_curriculum/checkpoint_200000
alright so we try a bunch of shit none of it works after a big humiliation infront of token bender i look at other examples that people have done. two of them one doesn’t use distance rewards the other one does but it’s simple euclidian distances.
turning off the distance reward
their envs are pretty simple actually so makes sense now in my case later i changed the food reward to 5000 which kind of did better so i reduced it to 500 and negative death to -1 and it well if ran for a long time it learnt how to find the local minima movements on how to survive. because food doesn’t exist let’s just not get negative rewards
re adding the curriculum
to fix that i reenabled curriculum and idk the run is very flaky it’s not really improving or
deproving, and in game it’s barely surviiving but i wanna wait till 400k steps see if it also get’s that lift off because previous run was also imrpoving the same way
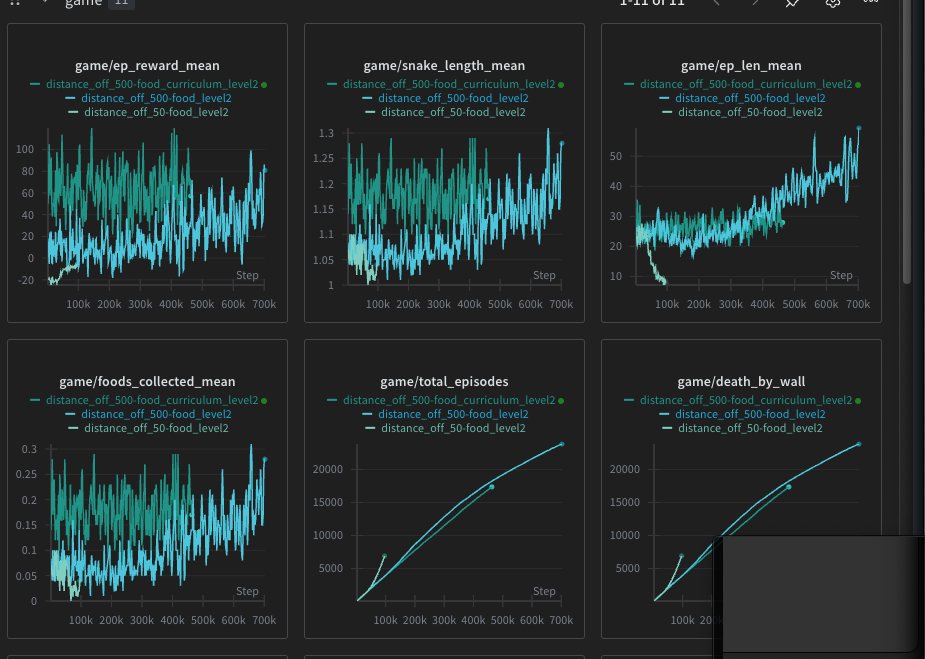 idk it looks idk better? ig it’s definetly better than the last one.
but there’s definetly a local minima problem :(
i think i forgot to add a length reward
length reward hmmmm
length scaling the reward and bonus points on reaching milestones
200k steps: so far it has been bad only prev run performed much better at this point. the distribution acts like how it did with those level 1 trains spread out with one side winning.
300k steps: i’m seeing the effect of the local minima every like 10 runs goddamn RL dude it’s only exploring at fucking 300k steps
500k ok this run is officially worse than the prev one
im gonna revert the length reward bs
i turned it off and reduced curriculum from 5 to 2 and it’s even more like level 1 training now i just wanna turn off the curriculum because the last one graphs were pretty good 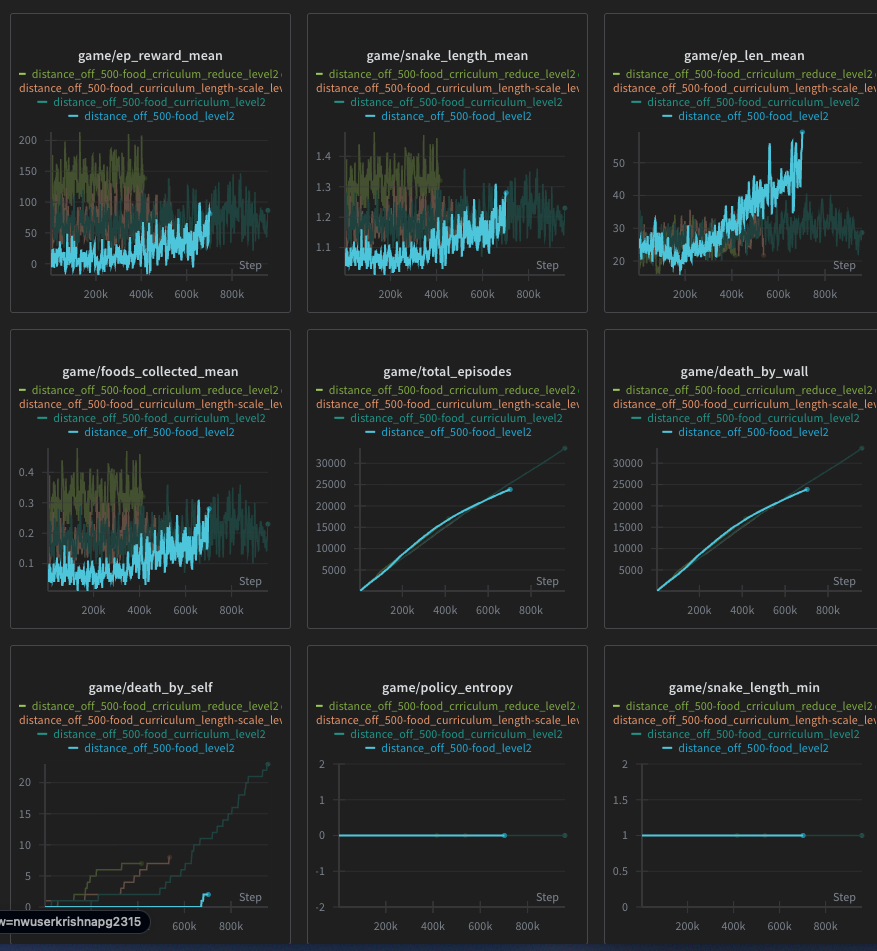
uv run snake_agent/train.py --run-name distance_off_500-food_level2_resumed --level 2 --resume /Users/krishna/Public/ml-experiments/snake-we/checkpoints/distance_off_500-food/level_2/checkpoint_500000 --timesteps 1000000 --n-envs 4
hmmmm i removed curriculum it improves i think i should add distance loss again but simpler this time closer the distance more the reward
turning distance on again
idk what the fuck i am doing but i changed it to euclid distance and more reward on closer reach… i think if i also dramatically increase positive rewards it’ll do much better who knows
300k steps: not seeing anything good yet let’s see game 700k steps: DUDE IT’S LEARNING TO TAKE FOOD like it’s kind of reaching for it in every 3 4 runs FUCK lets go 800k steps: so it regressed :sob: :sob: :sob: there’s a lot of problem with vf i am gonna fix it next but i gotta try the assymetrical distance reward.
assymetrical rewards
700k : it’s just finding the minima only but good surviving time avoiding walls and stuff . 800k:
value function clusterfuck
throughout this value function was constantly bad i now realize i should fix it’s convergence first
- reward normalization: VecNormalize(norm_reward=True, clip_reward=10) with save/load.
- rollout length: n_steps 2048 → 4096.
- PPO tuning: learning_rate 1e-4; vf_coef 1.0; clip_range_vf 0.2.
- shaping cap: distance shaping clipped to [-5, 5] per step.
- value logging: critic V(s) returned in /predict and shown in agent play.
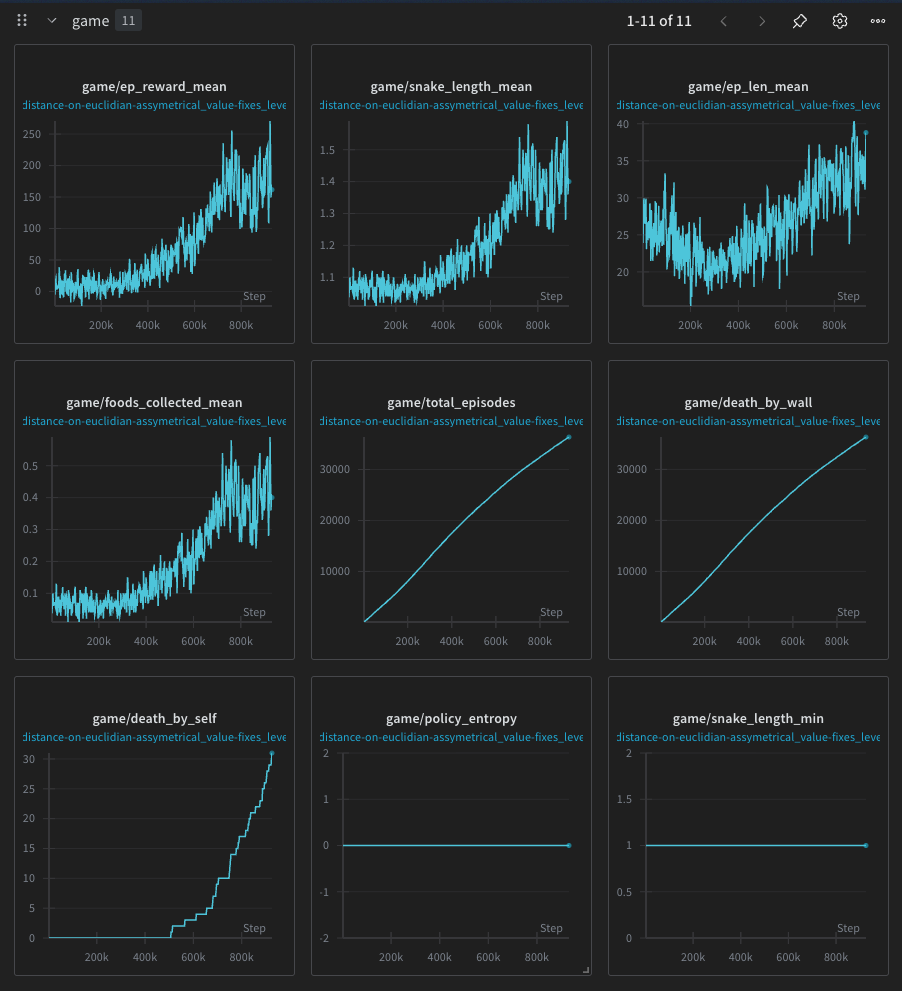 HOLY SHIT TT THAT WORKED
I AM SUCH A FUCKING RETARD I DIDN’T FIX THE VALU FUNCTION FIRST I WAS SO HELD UP IN THE BLOODY REWARD ISSUES…
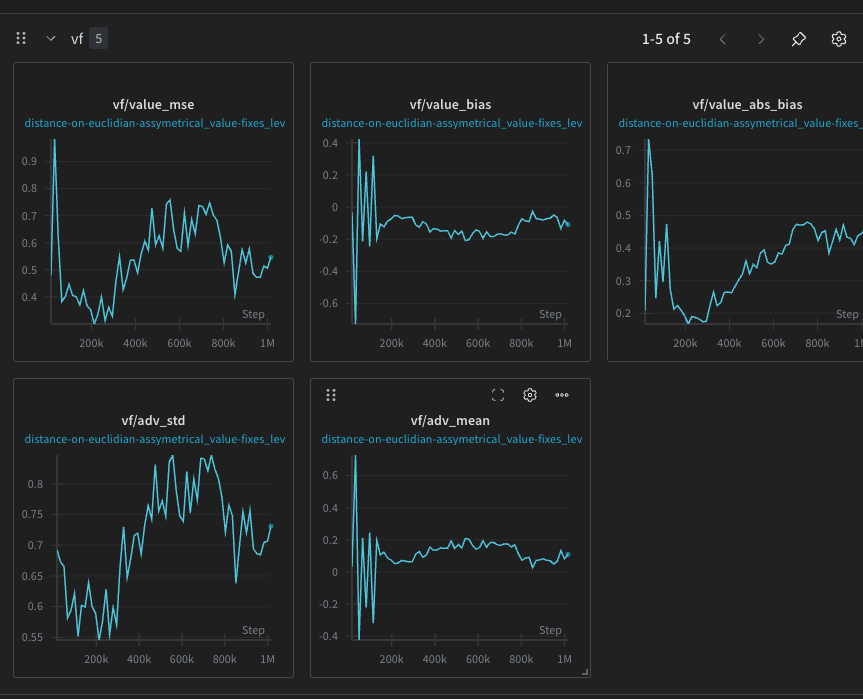
i did another run with a lower food reward like 100 and although the food collection graph looks similar the value mse etc doesn’t ofc reward mean is very much lower because it’s not getting as much… maybe i should shoot it up again prev run was doing better in the game play too it’s just killing itself after like getting 5 food at 900k steps alright that run was not really doing it reverted back to 500 for food