https://arxiv.org/abs/2508.19828
train models to index and organize data and retrieve to do query etc. i do believe that agentic memory is a data organization problem. sota uses AST for this but i don’t find that to be dynamic enough. so we keep a model in between.
the paper works alonmg the same line. they train the model in multi turn dataset where at each turn the model decides some things to extact from them and ig keeps them as facts, then retrieves related entries from the memory bank and the memory manager decides whether to add update delete it. hence evolving memory state. later an answert agent uses to retrieve from this memories and work off of them.
now actually the easiest way to do this is gepa this on a big model in my opinion give’s a good POC because finetuning the model would just be bringing that shit out as a capability.
RL finetuning for memory manager
the first part that maintains the memory doing the ADD, UPDATE, DELETE, NOOP tasks. their training uses a partially constructed memory bank and a new dialogue turn with information relevant to downstream QA.
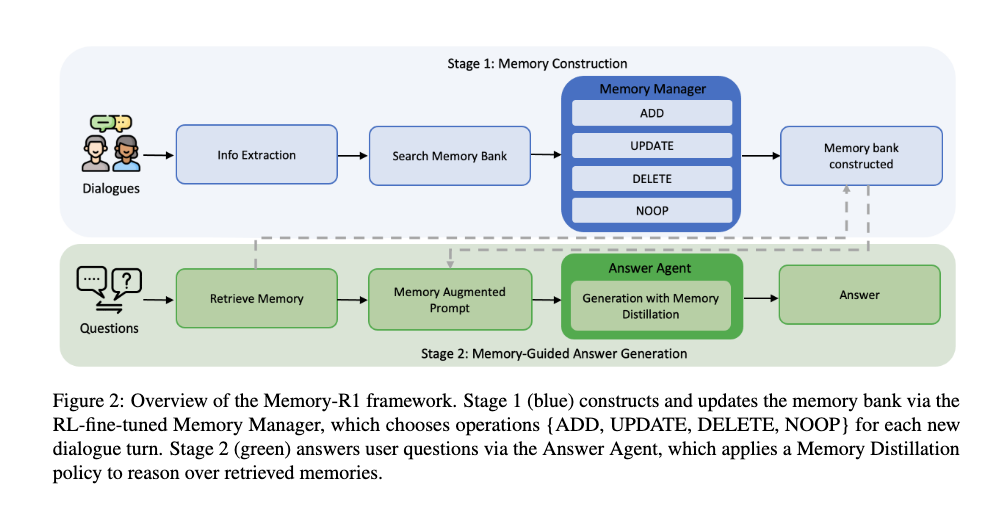
they train both the memory manager and retriever such that the base rewards depend on the answer and how correct it is.
it works like first they extract a base state of facts from the new statement or whatever and then pass it as a query on the base state of facts and then it tries to do the appropriate function on it like CRUD so the the managed memory is dynamic.
how does the answer agent work?
they doe a similarity search for the top-k results for whatever query on top of that it applies a memory distillation policy to shrink down the relevant results. this memory distillation policy is trained.
but this seems like such a bad strat overall like shouldn’t there be a temporal factor and an intensity factor. like how does the distillation figure that shit out? ig the model can result by itself. the agent really needs to be just trained to find the relevant information.
results
they use the LOCOMO dataset which is just 10 multi-turn dialogues each ~600 turns on averager and only 26k tokens average . bro that is so ass 20k im pretty sure claude can hold in the damn context
the results feel how do i say. stupid without calling this bs bs
comparing it against mem0 and locomo system etc they share the results.
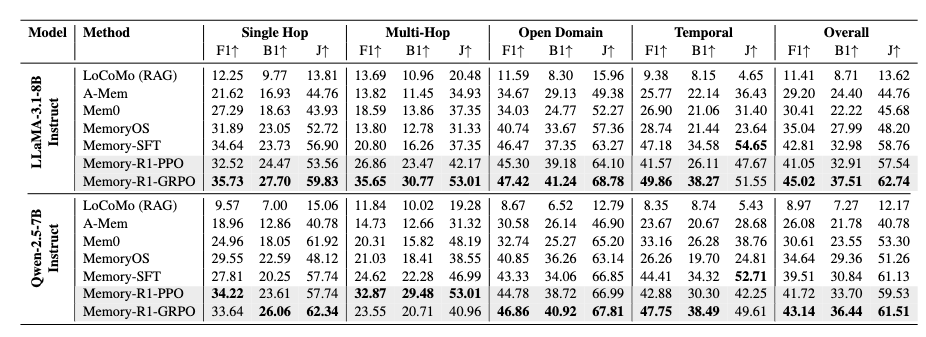
ig that’s a good improvement but this is not an official benchmark i would say.
hmm can i use this or train this with prime RL? should be an easy train and test if i get the appropriate data.