https://arxiv.org/abs/2603.13875
titans learning to memorize at test time flashbacks
what this paper introduces/does
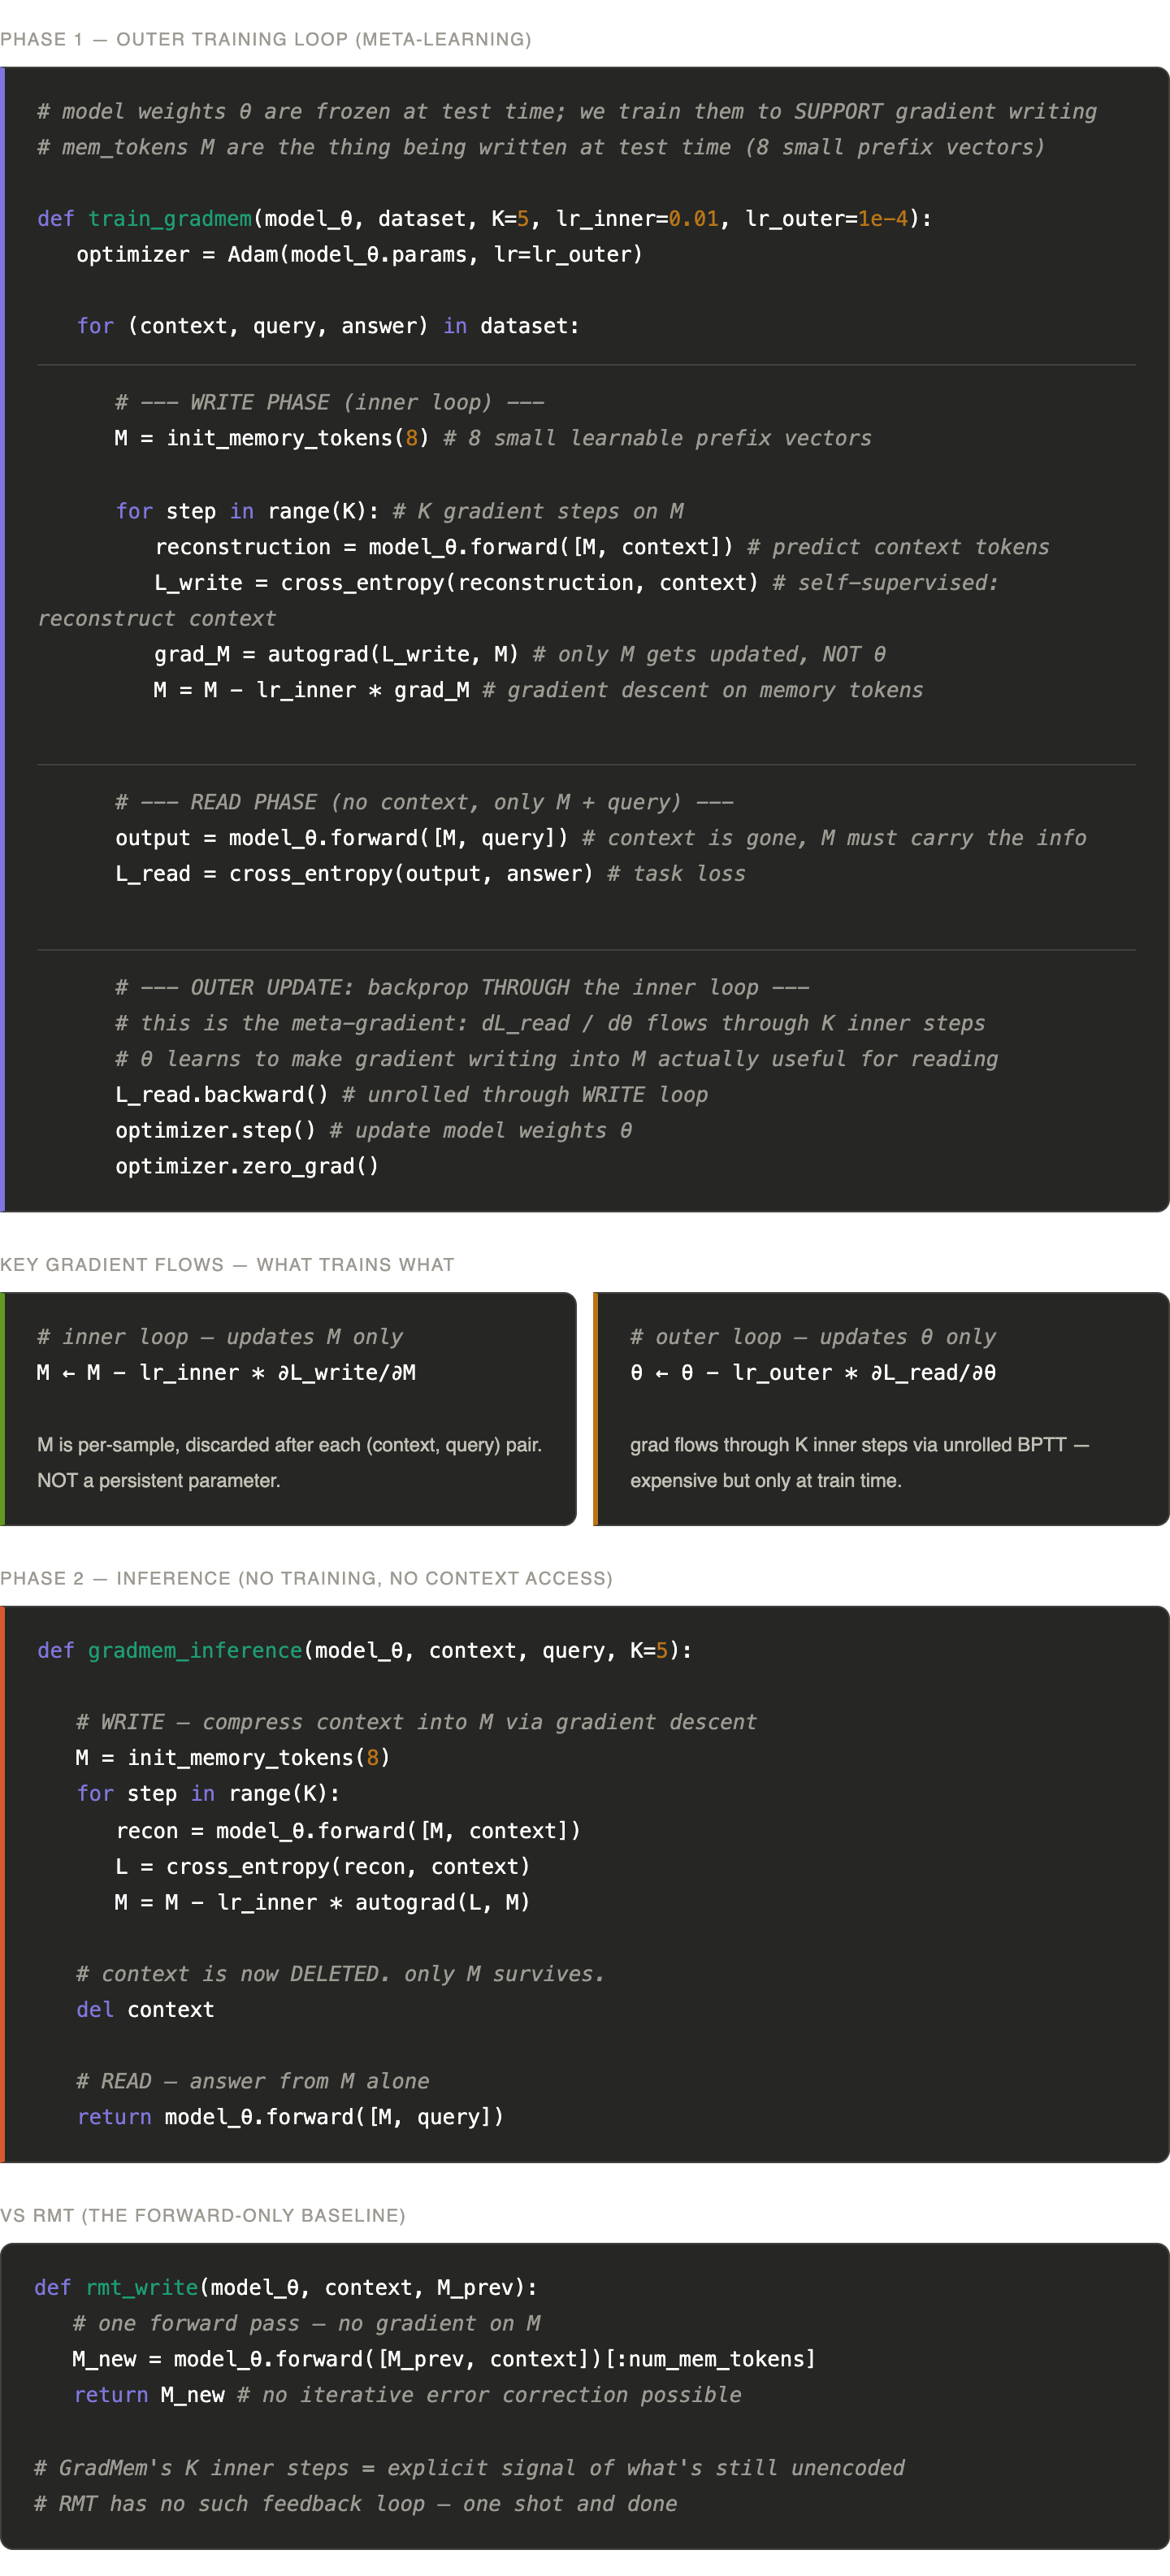
they want to use grad steps to use and update memory priors over an LLM to make it efficcient than KV cache over long horizion. the LLM stays frozen i think.
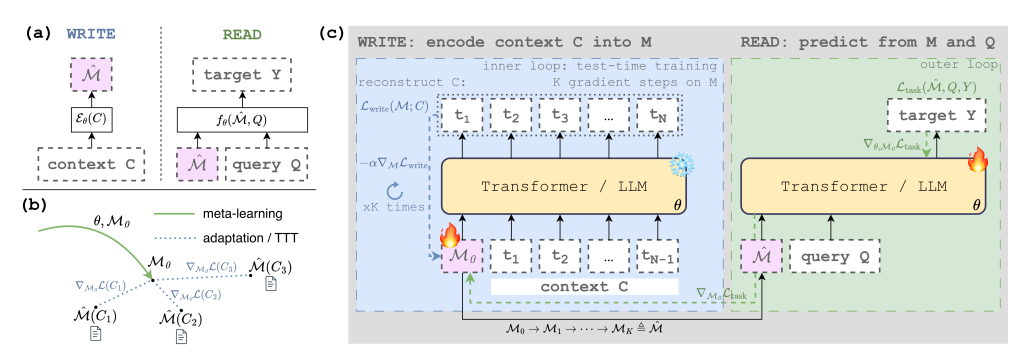
we have the context being passed , query and target result they try to compress into a small fixed size memory. since query is the actual prompt as to what to do with the information or it’s compressed version is just the base state of information that the model needs to give the correct result.
and is a causal language model with params denotes the probability assigned by the model to an output sequence conditioned on input . so the equation of a standard model is :
they have a two parts,
-
WRITE which is the encoder converting to as
-
**READ decode using memory and query **
the actual training